# Hi Y'all! ---  ---  ---  --- <!-- .slide: data-background="white" --->  --- # Background: What we are building --- 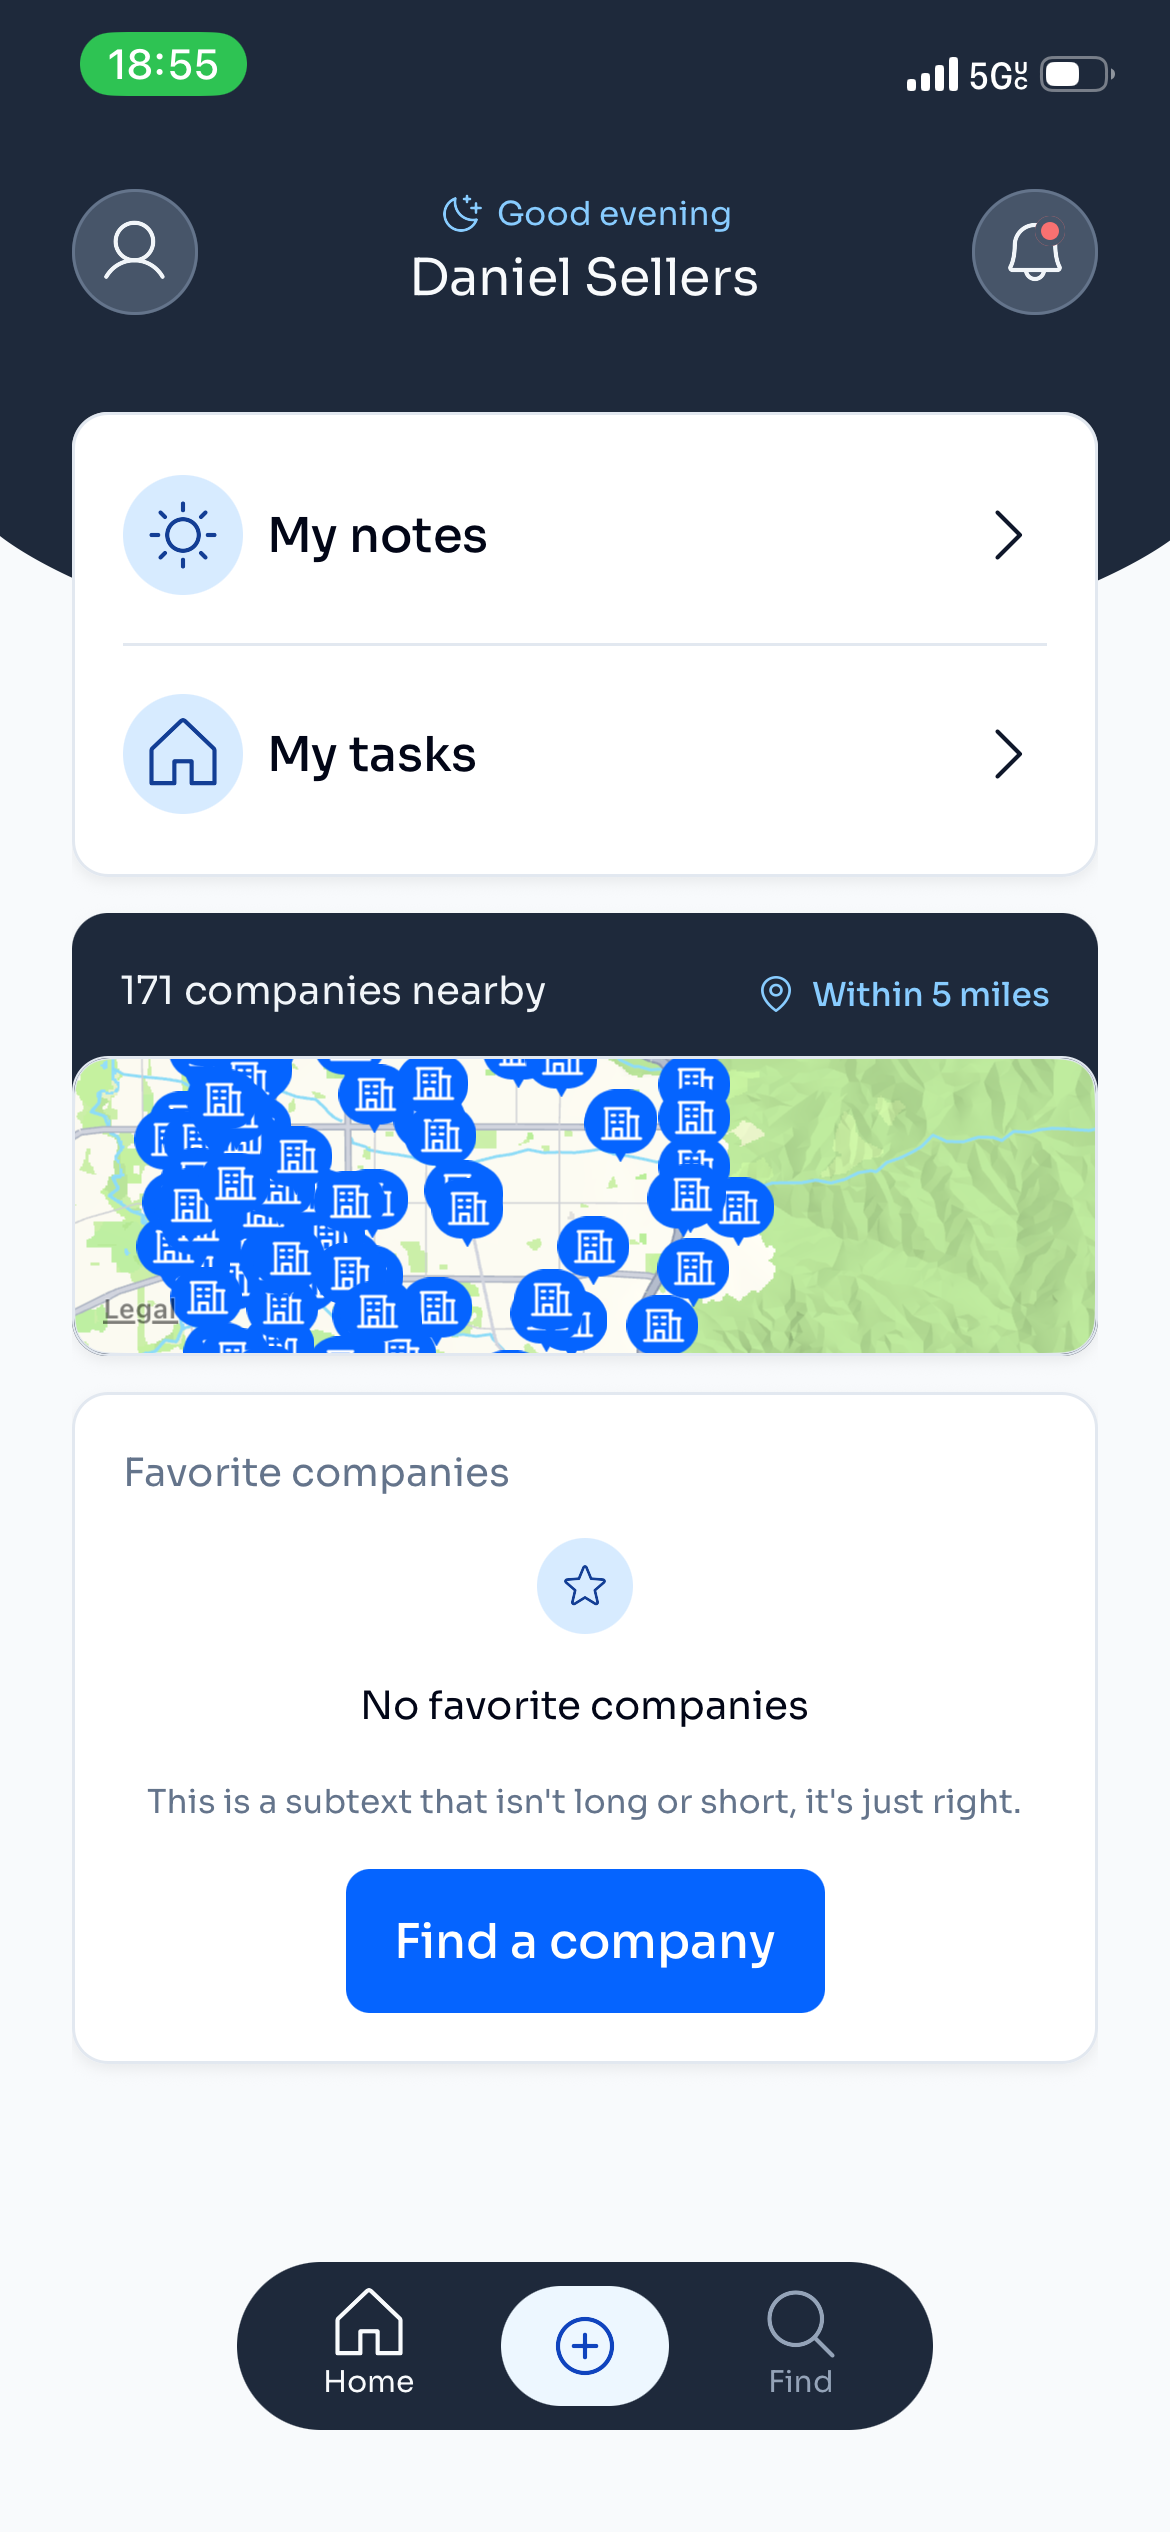 --- 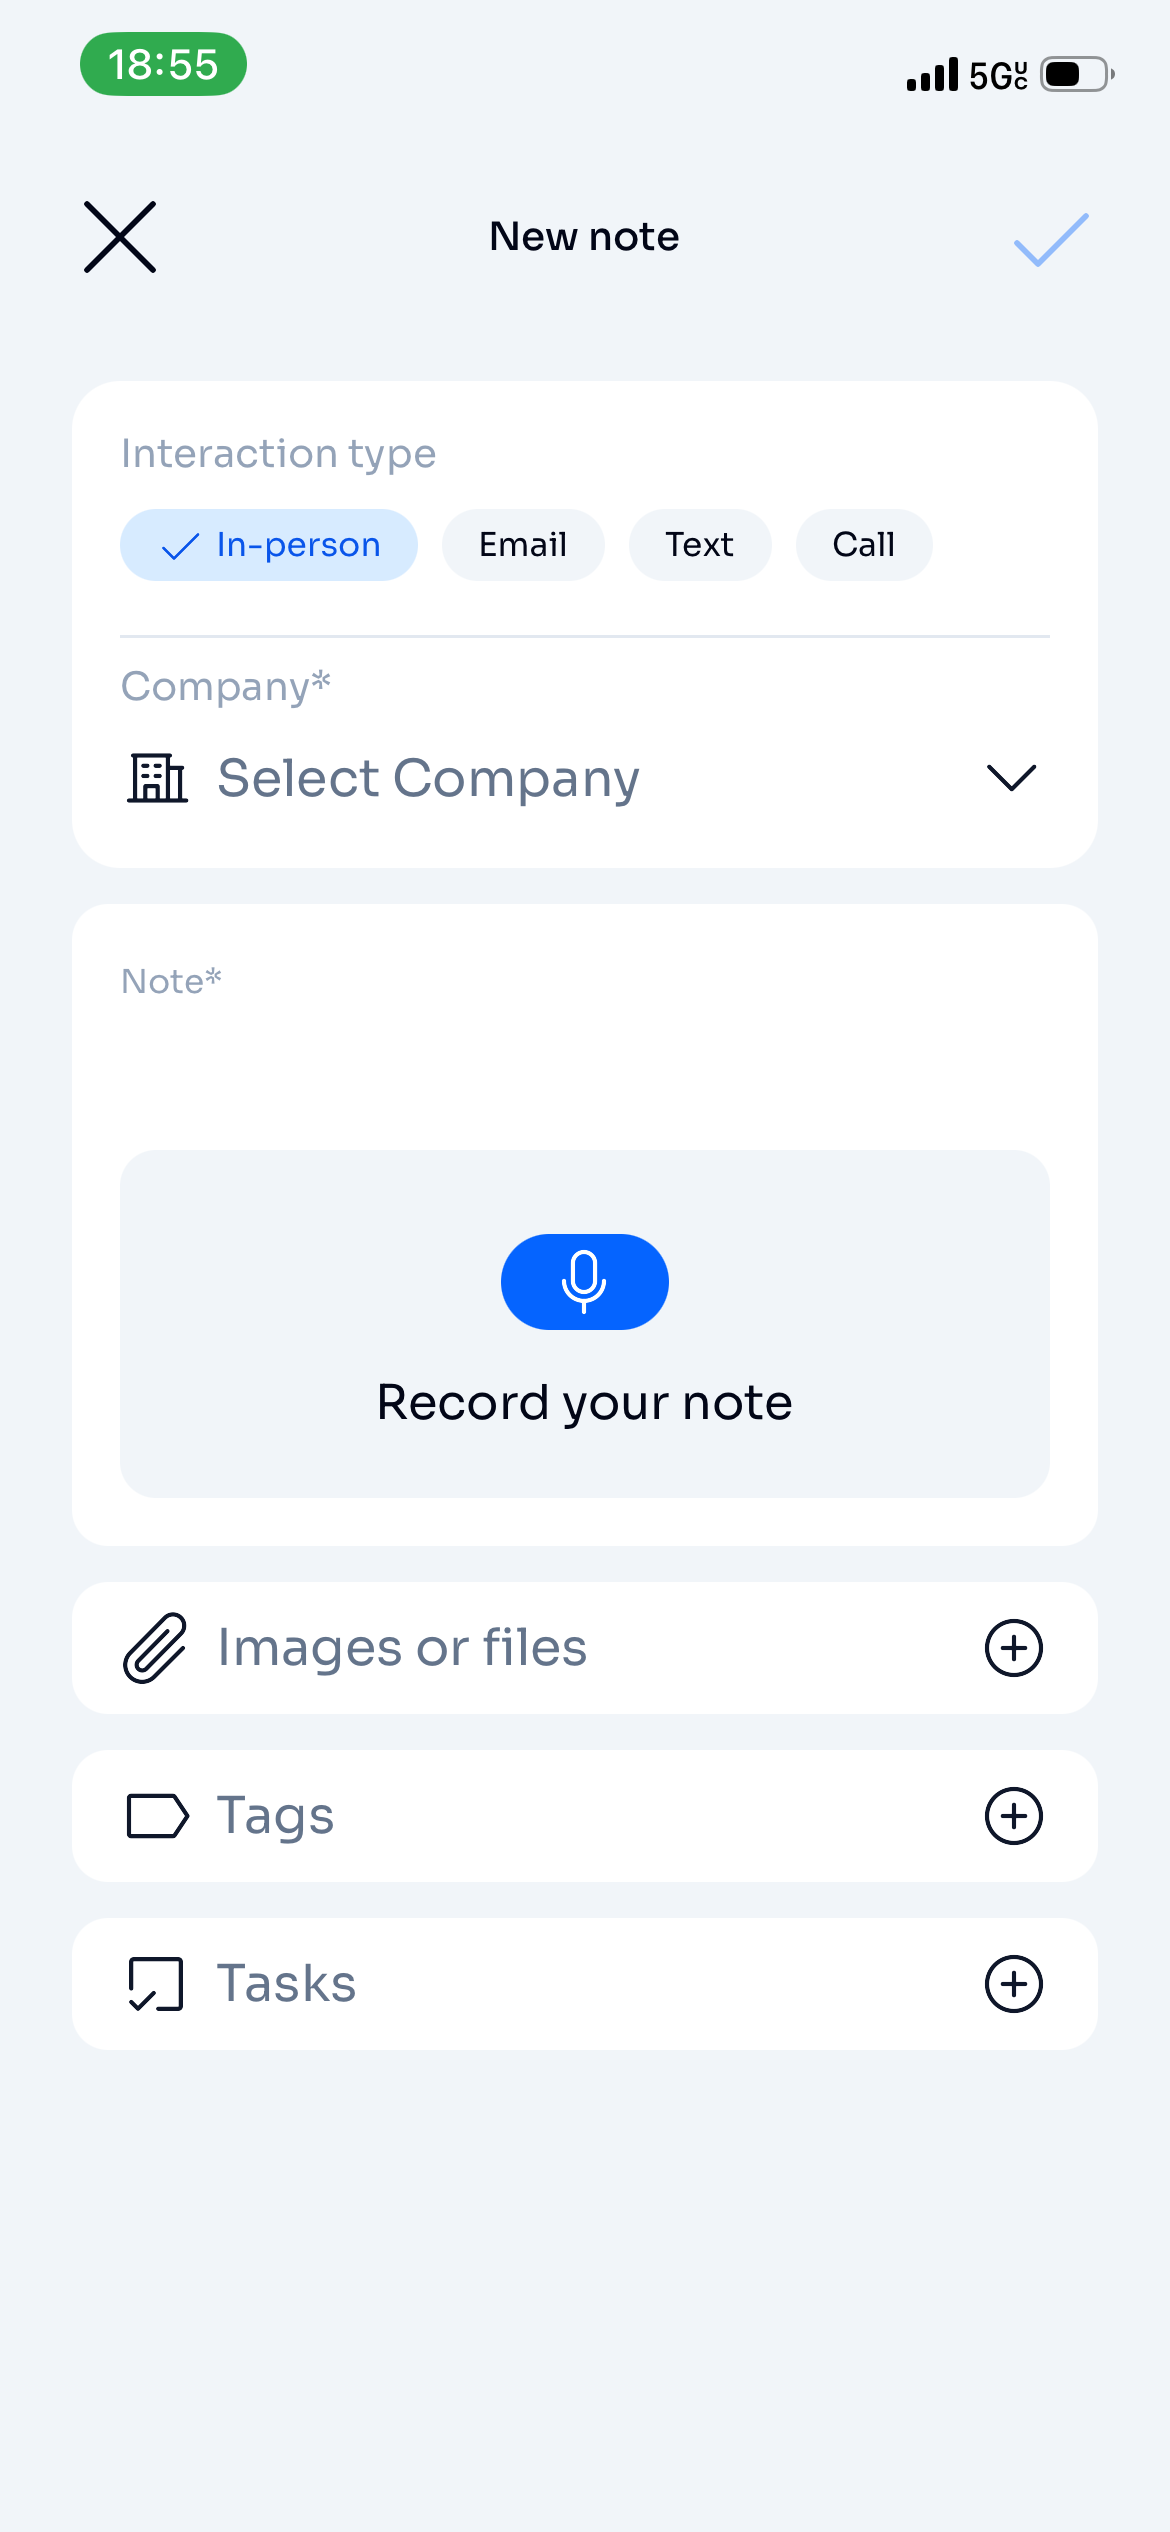 --- # Now a digression --- # The Three\* Types of AI businesses --- ## 1. Building Models for others (OpenAI, Anthropic, Google, Mistral, etc.) --- ## 2. Accelerated by frontier models --- ## 3. Building, or fine-tuning, models for internal use --- # Voze is a Type 2 business\*\* --- ### \* This is my mental model... use it where helpful ### \*\* For now --- <!-- .slide: data-background="https://media3.giphy.com/media/v1.Y2lkPTc5MGI3NjExcTY1dzkwMTB3aDd5ZzU3ODB6dThqcWdveWpoNndwODM2MjN6a2UzcSZlcD12MV9pbnRlcm5hbF9naWZfYnlfaWQmY3Q9Zw/JY2qOhbPnmJOnVVQRC/giphy.gif" --> --- # Why Does This Matter? --- ## When do we all transition from 2 to 3? ### Will we ever need to? --- # Will the asymptote be high enough? --- <!-- .slide: data-background="https://media3.giphy.com/media/v1.Y2lkPTc5MGI3NjExZmtzM2F6NWcyOGc5Mmx2MGdqaGkxN2RzMTJpcTA4bDMzeHpkNGZqMiZlcD12MV9pbnRlcm5hbF9naWZfYnlfaWQmY3Q9Zw/ZDhPlli6gMh44/giphy.gif" --> --- # What we've learned over the last 12 months --- 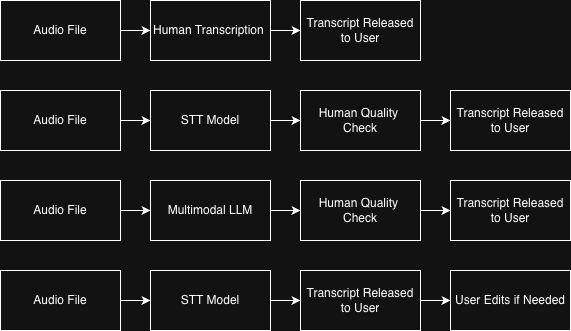 --- <!-- .slide: data-background="https://media1.giphy.com/media/v1.Y2lkPTc5MGI3NjExNHZveGlweTRlaWtidjUyYmM5ZmZzeTZubDJramE3N3M4NGc5emx2ZyZlcD12MV9pbnRlcm5hbF9naWZfYnlfaWQmY3Q9Zw/cjyVveMCMgunS/giphy.gif" --> --- # Deepgram... hated silence --- <!-- .slide: data-background="https://media0.giphy.com/media/v1.Y2lkPTc5MGI3NjExYXc1Nm82eHJubHlhOHlwMWxycWFvYjN1N3cyNWZobDlsMWd4emxqaiZlcD12MV9pbnRlcm5hbF9naWZfYnlfaWQmY3Q9Zw/snrDtXJBEiZwY/giphy.gif" --> --- --- # Deepgram plus empty audio checks --- # Multimodal LLMs have entered the chat --- ``` def get_prompt(client_type: str): prompts = { 'tire': GEMINI_AUDIO_TRANSCRIBE_PROMPT } return prompts.get(client_type, GEMINI_AUDIO_TRANSCRIBE_PROMPT) ``` --- ``` def transcribe_audio_gemini(file: StorageStreamDownloader, client_type: str=''): audio_bytes = file.read() if audio_bytes: # Base configuration config = { 'response_mime_type': 'application/json', 'response_schema': TRANSCRIPTION_SCHEMA } response = client.models.generate_content( model=gemini_transcription_model, contents=[ get_prompt(client_type), types.Part.from_bytes( data=audio_bytes, mime_type='audio/m4a', ) ], # generation_config=types.GenerationConfig(**config) if config else None ) return response.text else: return '' ``` --- ``` TRANSCRIPTION_SCHEMA = { "type": "object", "properties": { "transcript": { "type": "string", "description": "The transcribed text from the audio" }, "confidence": { "type": "number", "description": "Confidence score of the transcription (0-1)" }, "language": { "type": "string", "description": "Detected language of the audio" }, "metadata": { "type": "object", "properties": { "duration_seconds": {"type": "number"}, "speaker_count": {"type": "integer"}, "has_background_noise": {"type": "boolean"} } } }, "required": ["transcript"] } ``` --- # Building tooling for the future --- <!-- .slide: class="center-large" ---> 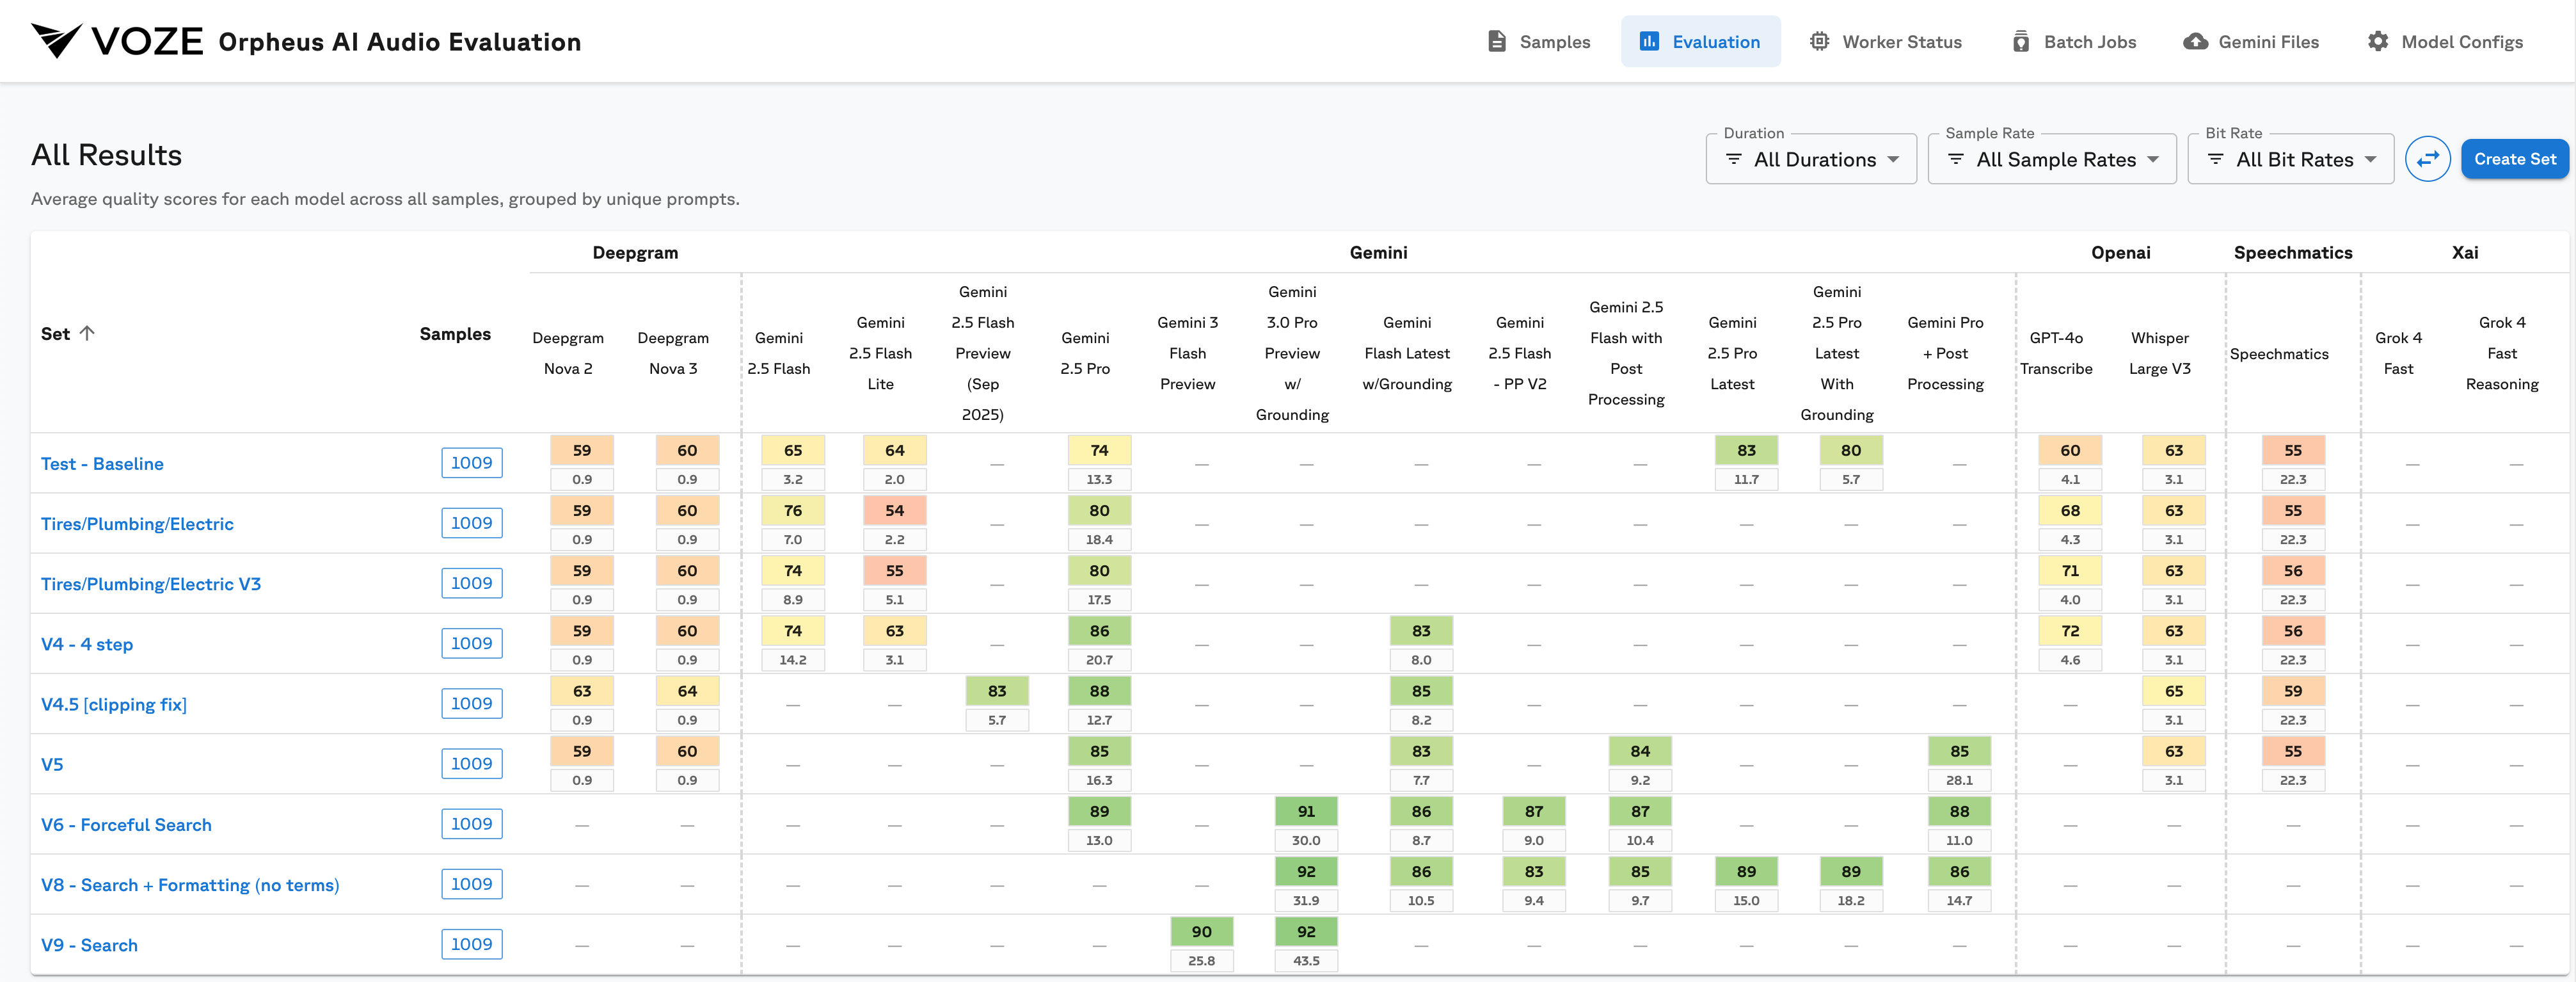 --- 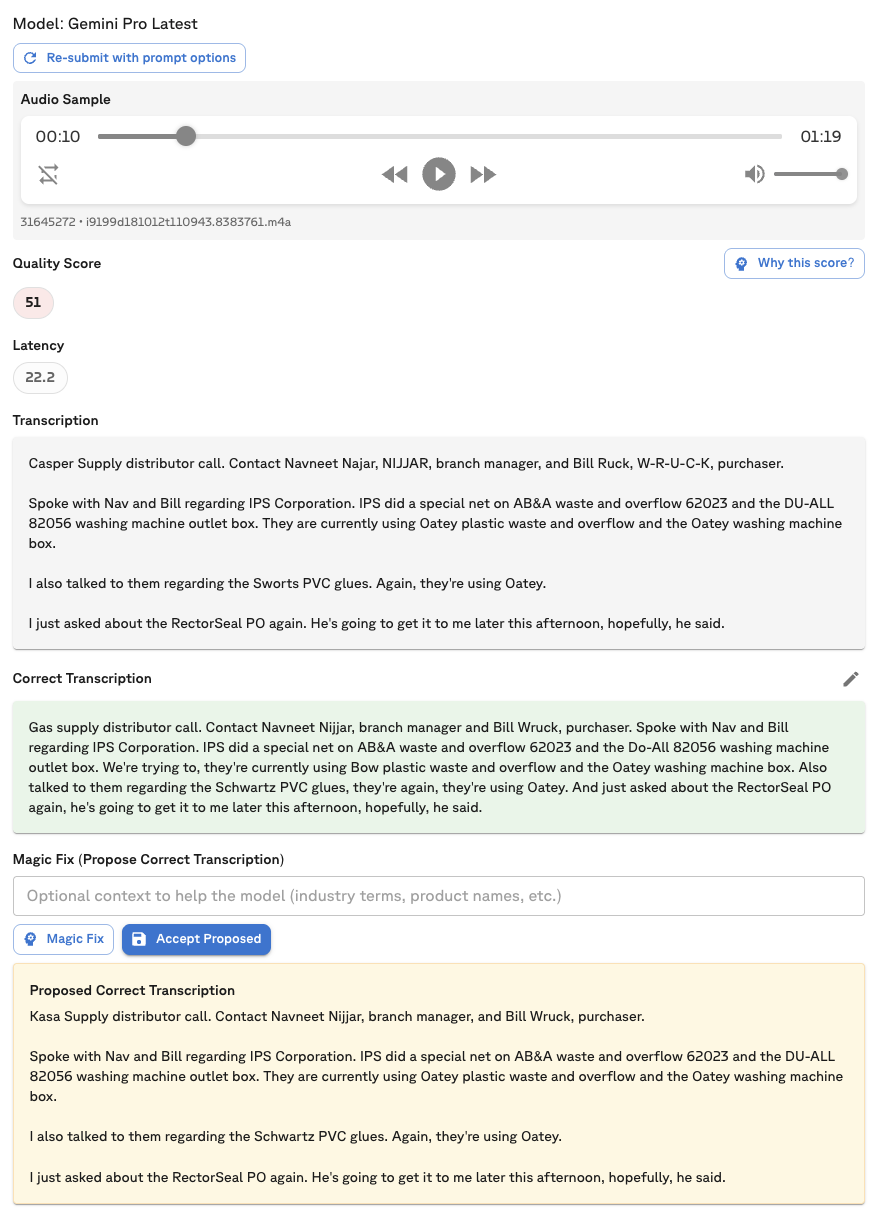 --- <!-- .slide: class="center-large" ---> 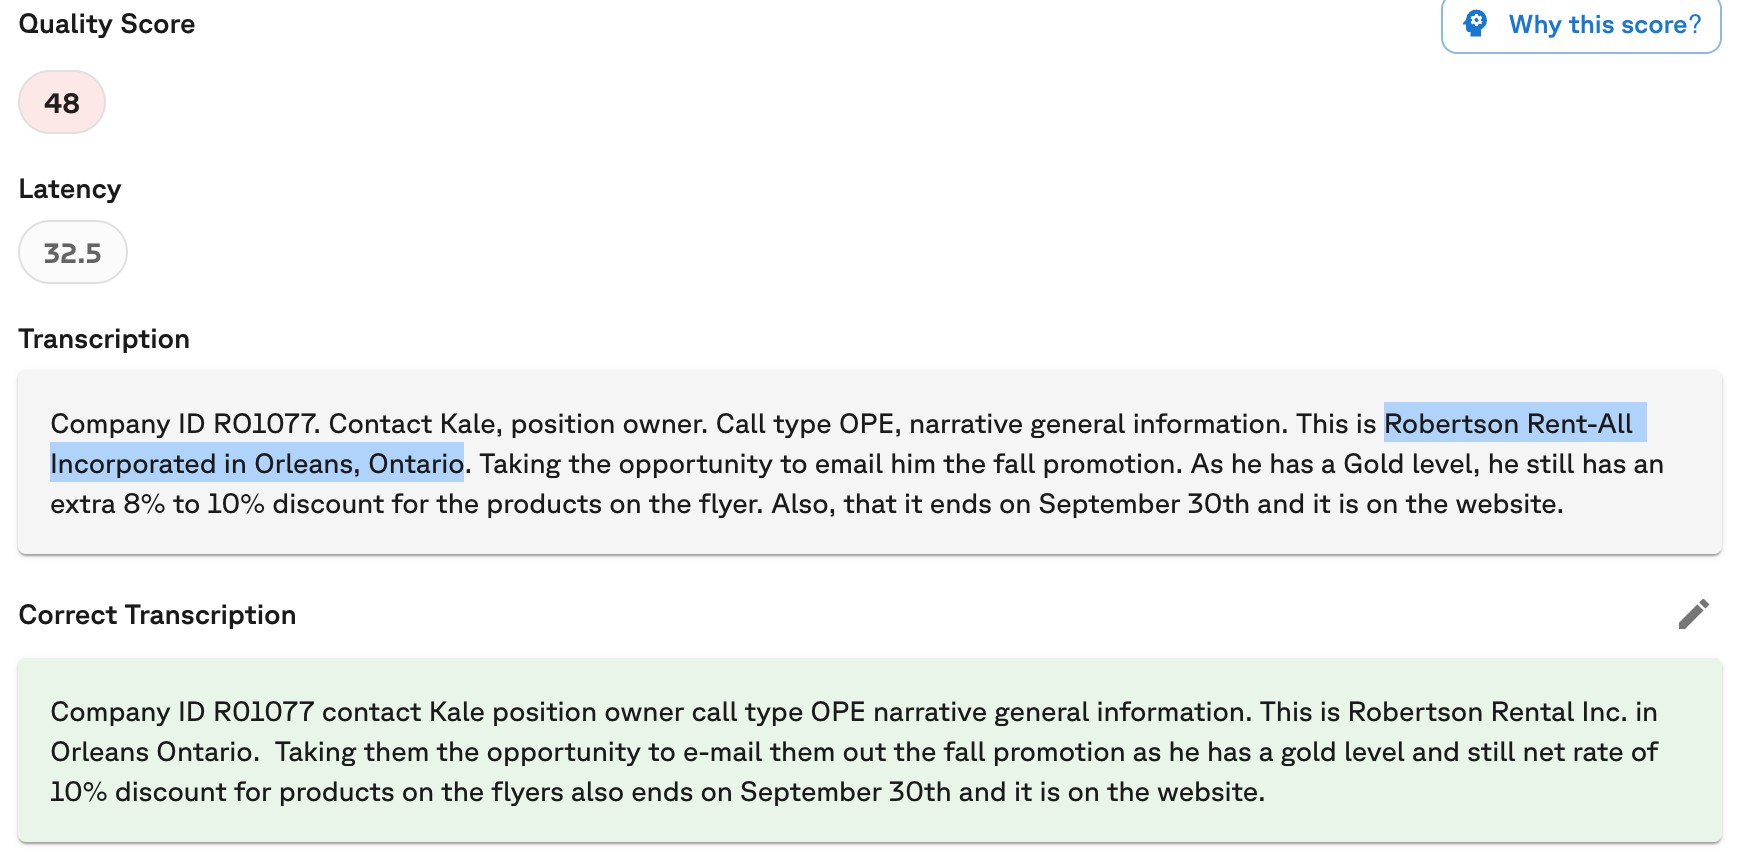 --- 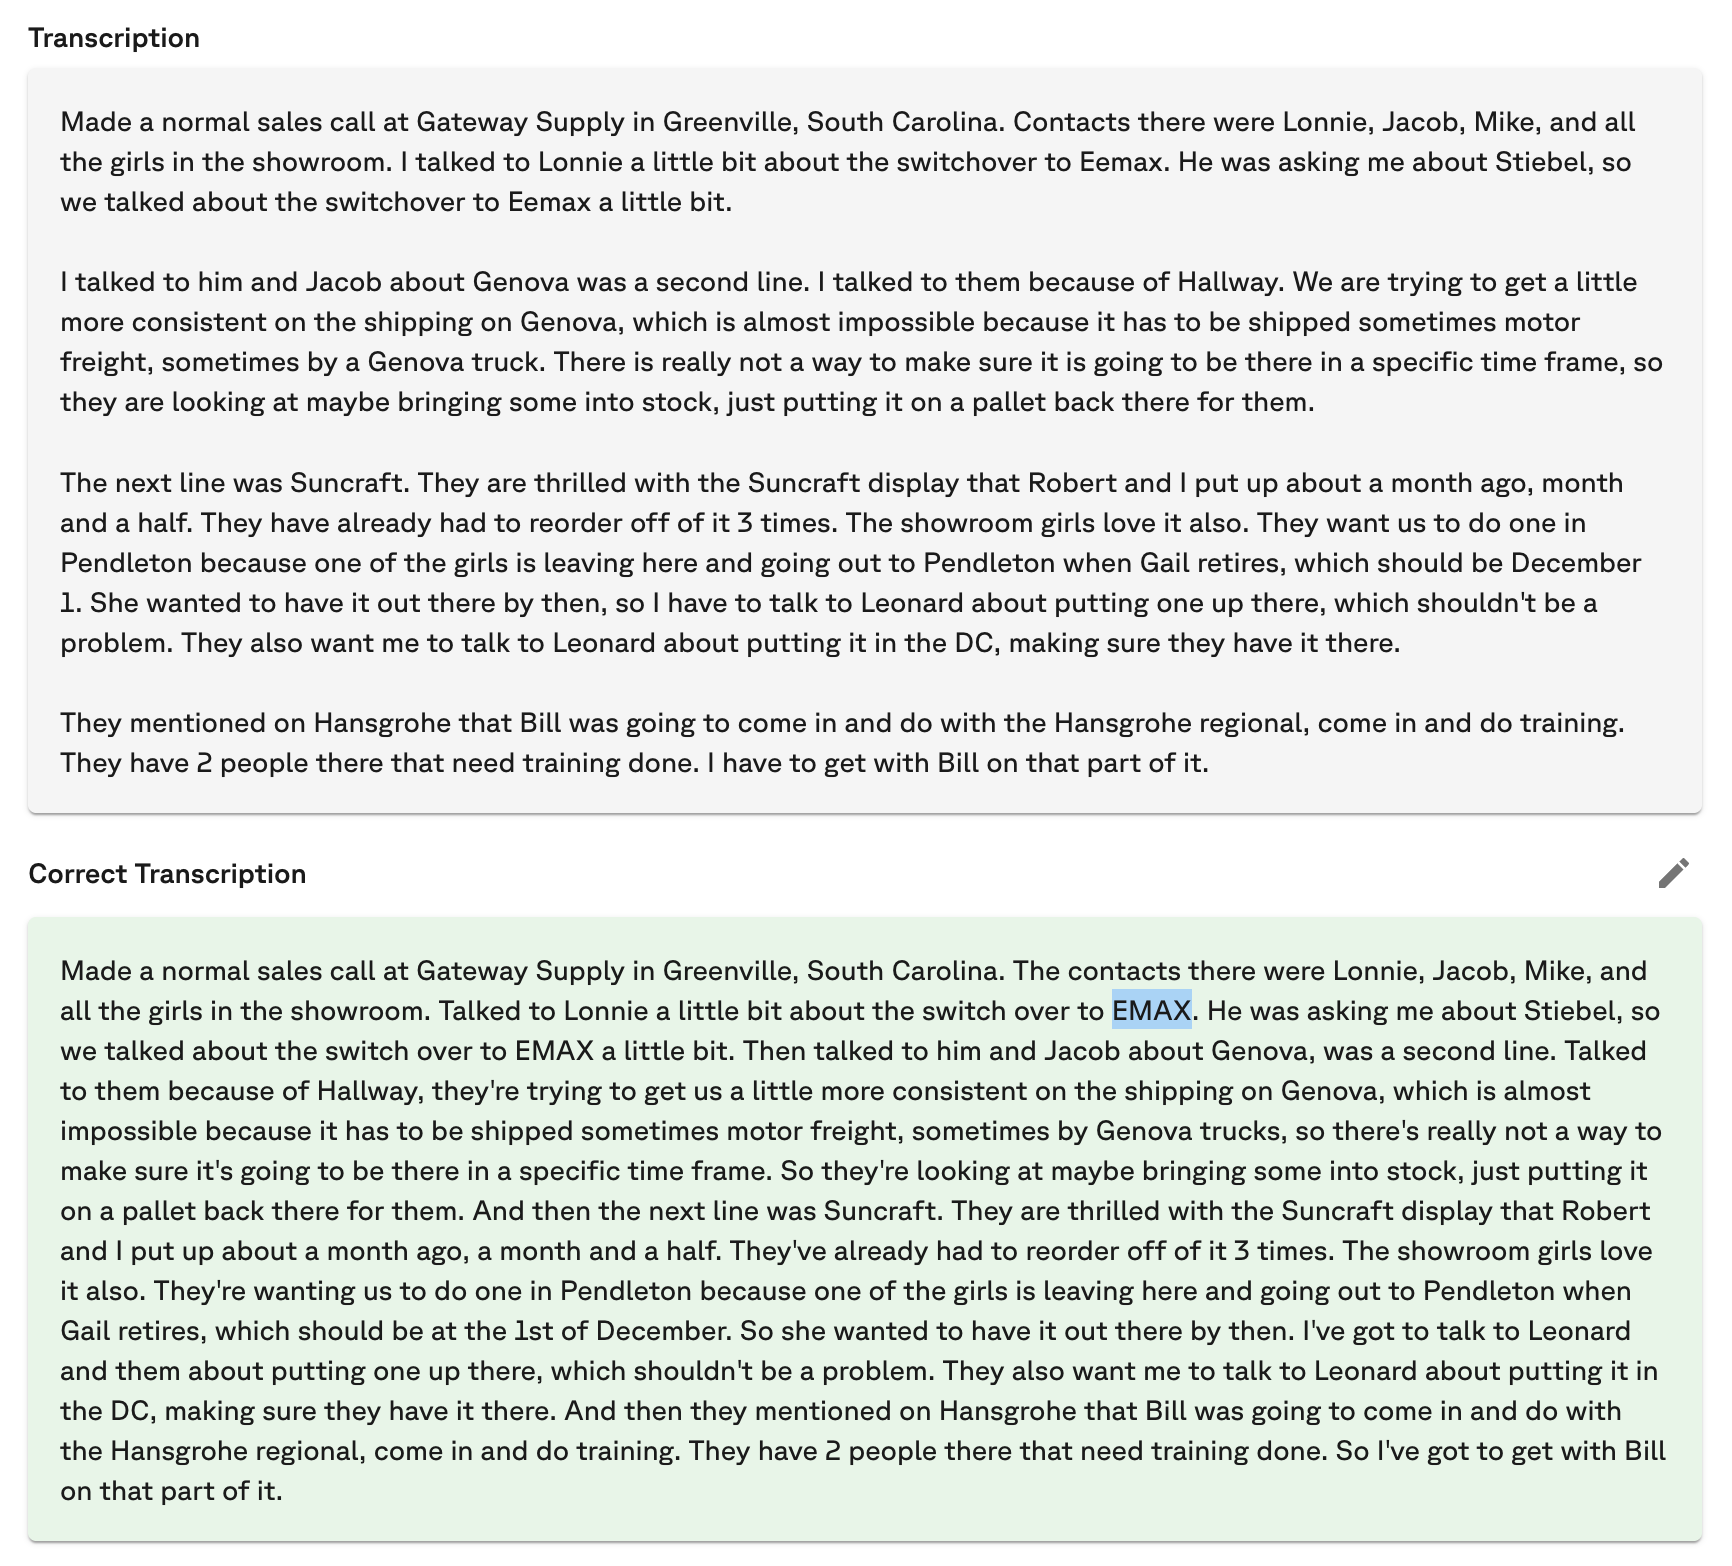 --- 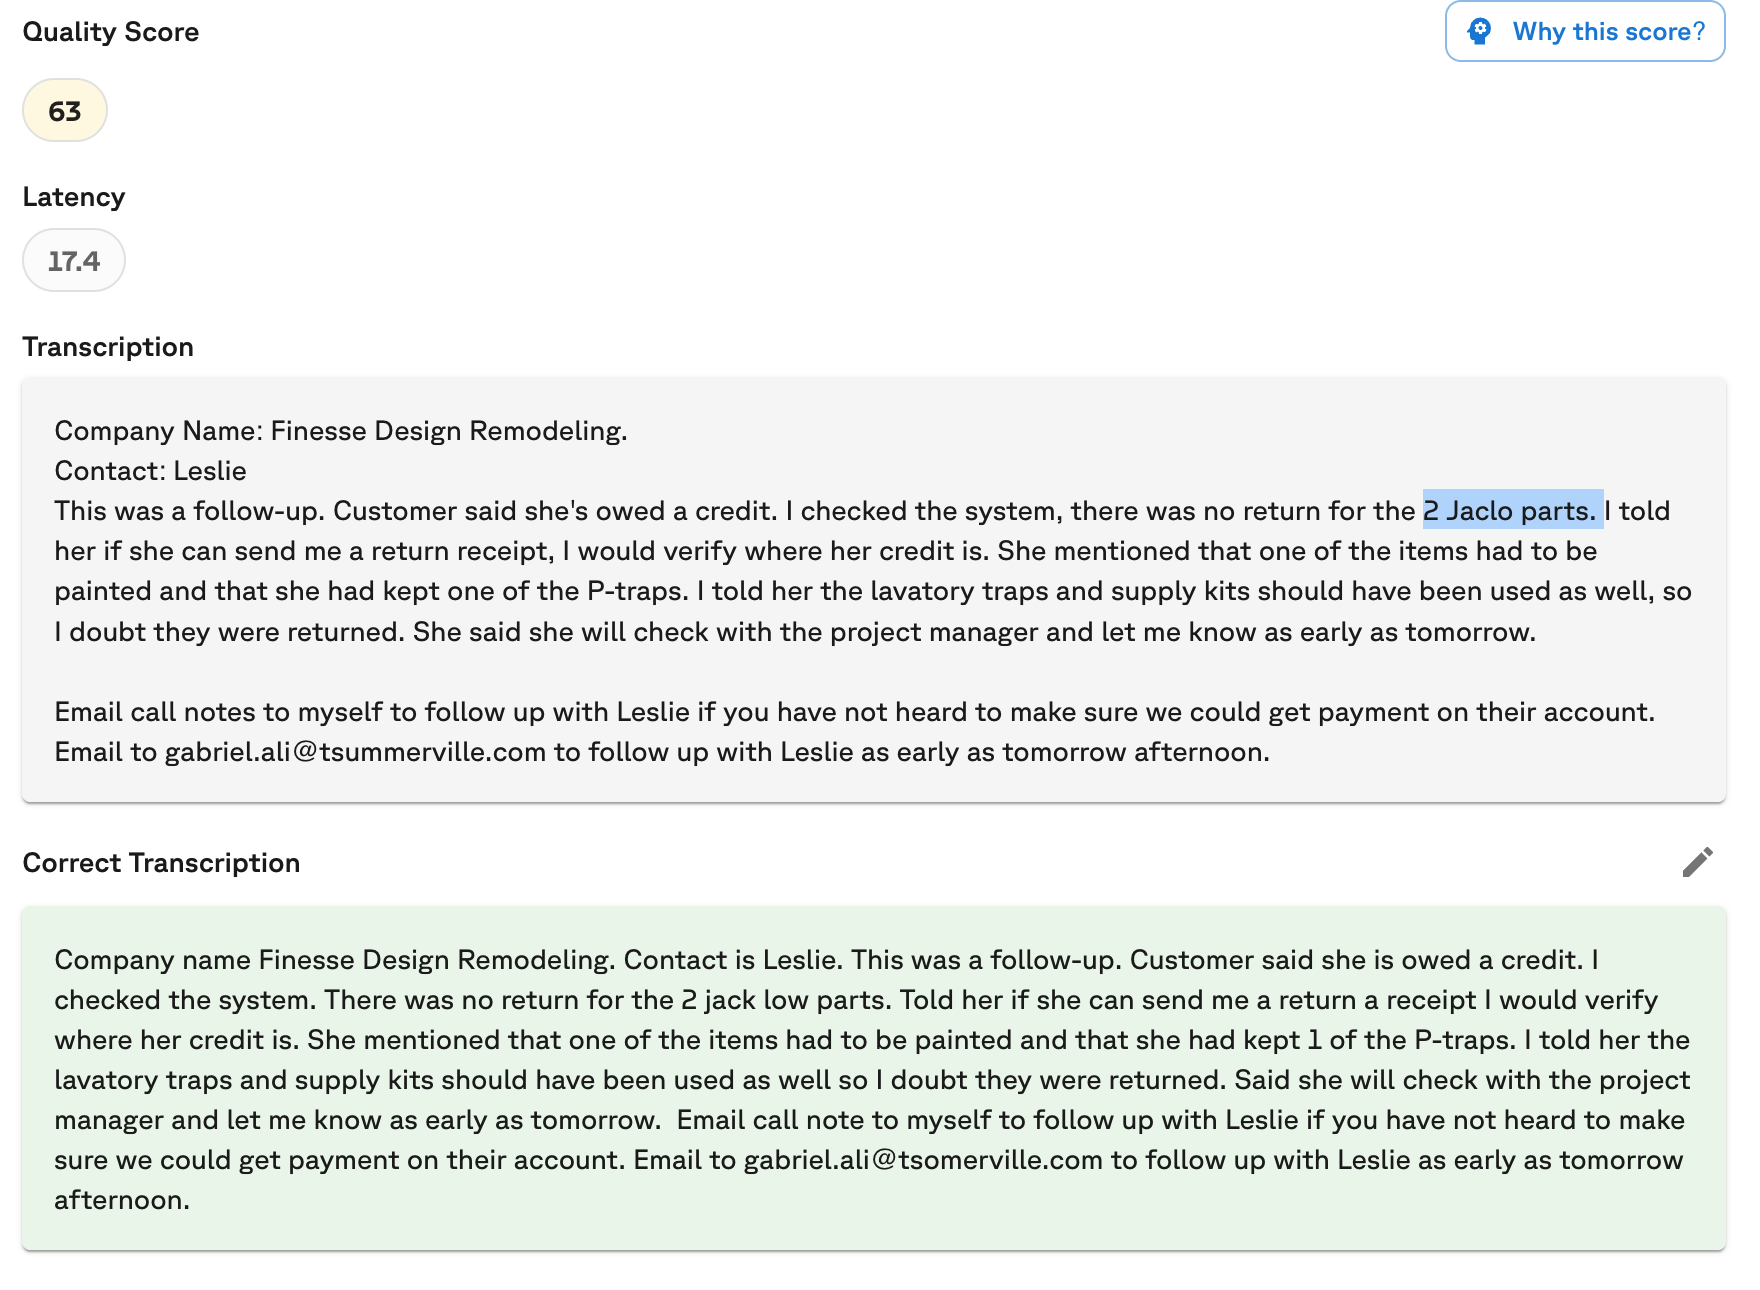 --- # Other random lessons learned --- ## Bitrate matters, at least a little --- ## Some audio is not really recoverable or usable ---  --- # What's next? --- <!-- .slide: class="questions" --> # ?s --- ## Daniel Sellers ### daniel[at]designfrontier.net ### designfrontier.net ### @daniel_sellers ### Voze.com